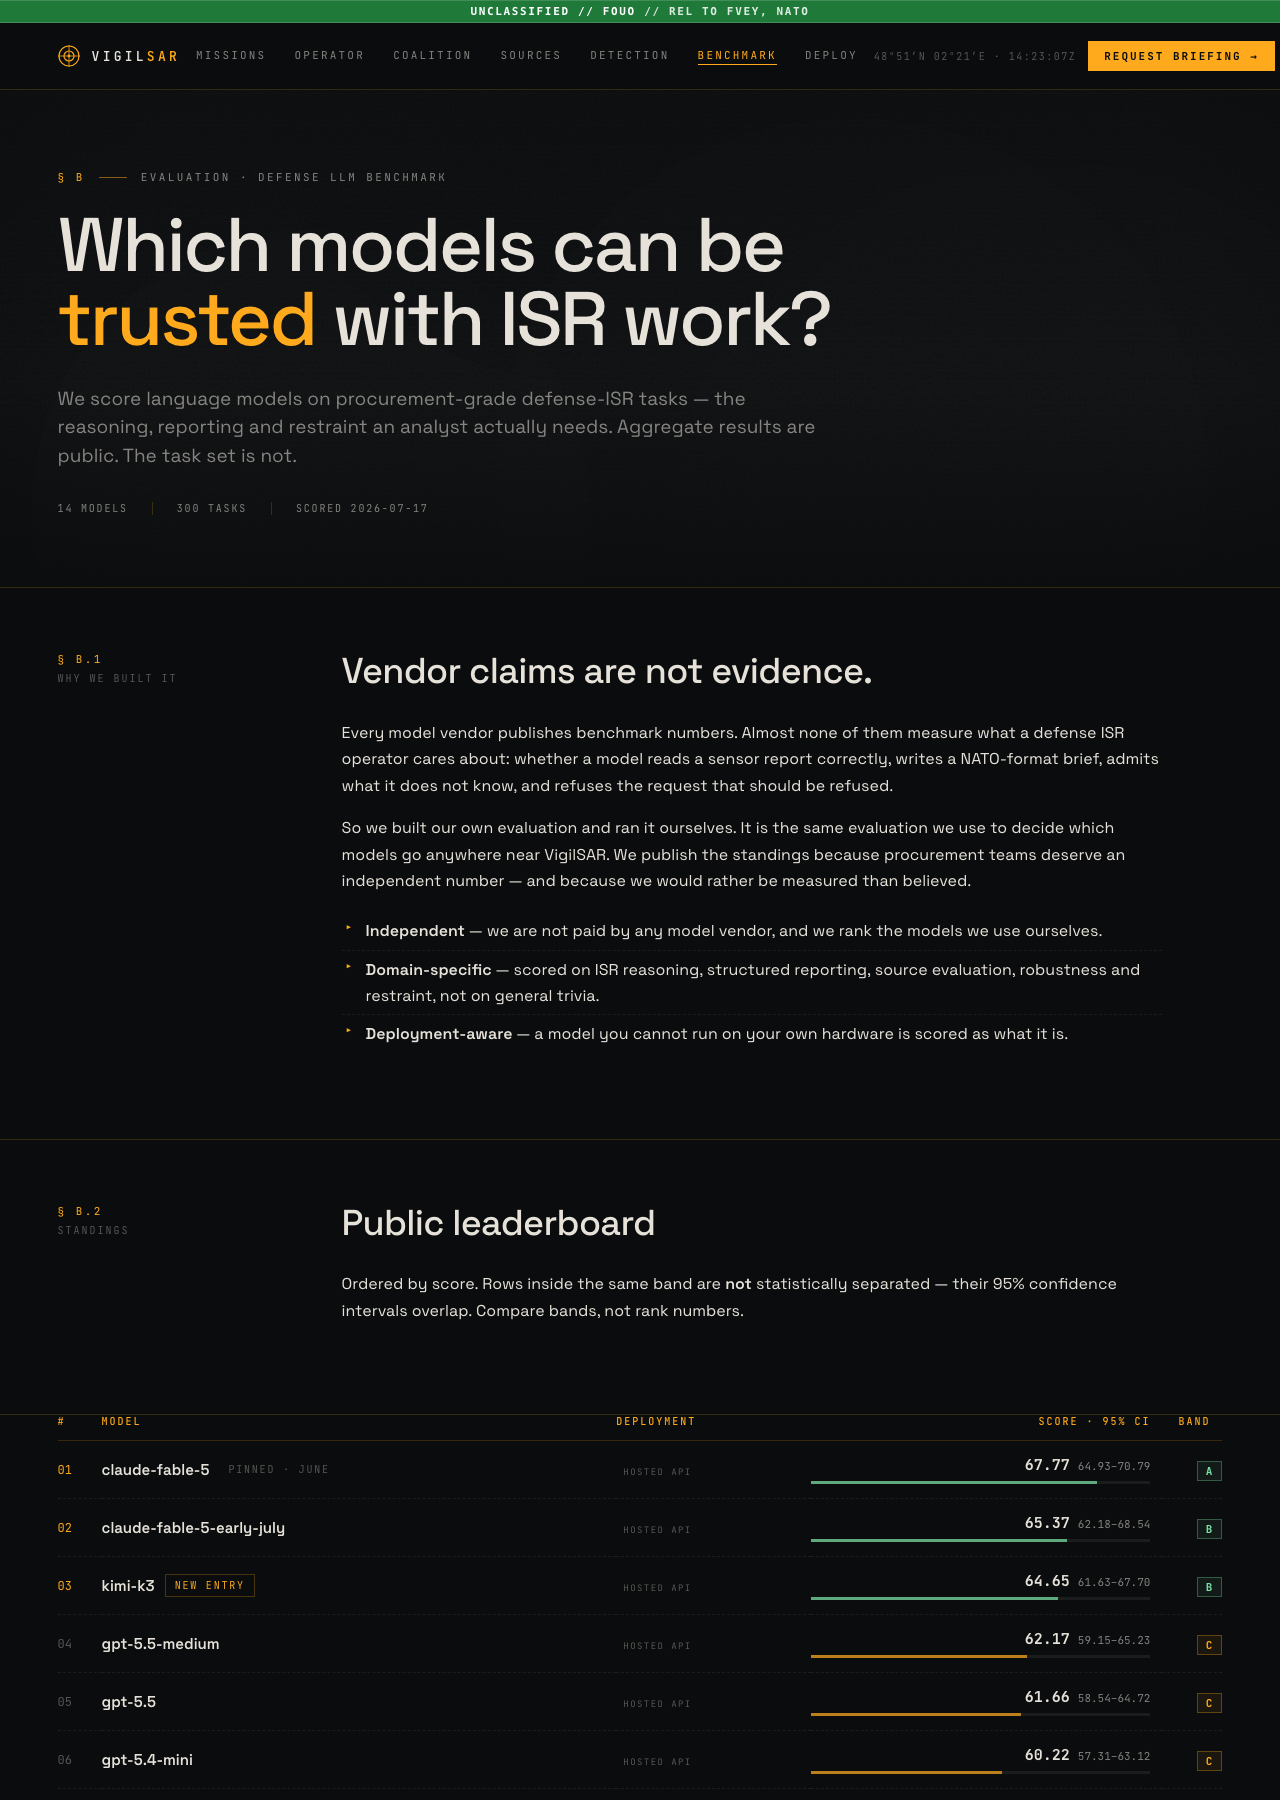
In the realm of defense-ISR (Intelligence, Surveillance, and Reconnaissance) software, VigilSAR has taken a significant step by releasing a public LLM leaderboard. This benchmarking effort evaluates how well various language models can perform the complex reasoning, reporting, and restraint required in intelligence tasks. Unlike typical AI benchmarks, VigilSAR’s approach emphasizes trustworthy performance over trivia, making it highly relevant for defense applications.

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The evaluation was conducted on a set of 14 models across 300 tasks, with scores recorded as of July 17, 2026. Importantly, the results shared are aggregate and transparent, but the task set remains private. This deliberate secrecy ensures models cannot train or fine-tune on the specific tasks—preserving the integrity of the evaluation. A private held-out set exists, and the gap between public and private scores serves as a marker for potential memorization or overfitting.
Current standings use confidence bands rather than precise ranks, reflecting the statistical overlap among models. Leading the pack is Claude Fable 5, pinned within Band A at 67.77. A notable newcomer, Kimi K3 by Moonshot, debuts impressively at 64.65 in Band B, outperforming every GPT and Gemini model on the leaderboard. The results highlight how different models are positioned within a spectrum of reliability and performance, with deployment realities and economics factored into scoring.
Why does VigilSAR keep the task set private? The site explicitly states that “vendor claims are not evidence,” emphasizing independent evaluation over vendor marketing. The goal is to determine which models can approximate their own product capabilities, rank the models they trust, and maintain a neutral, vendor-agnostic perspective. This transparency—through bands, confidence intervals, and cost metrics—aims to foster honest comparisons in a high-stakes field.
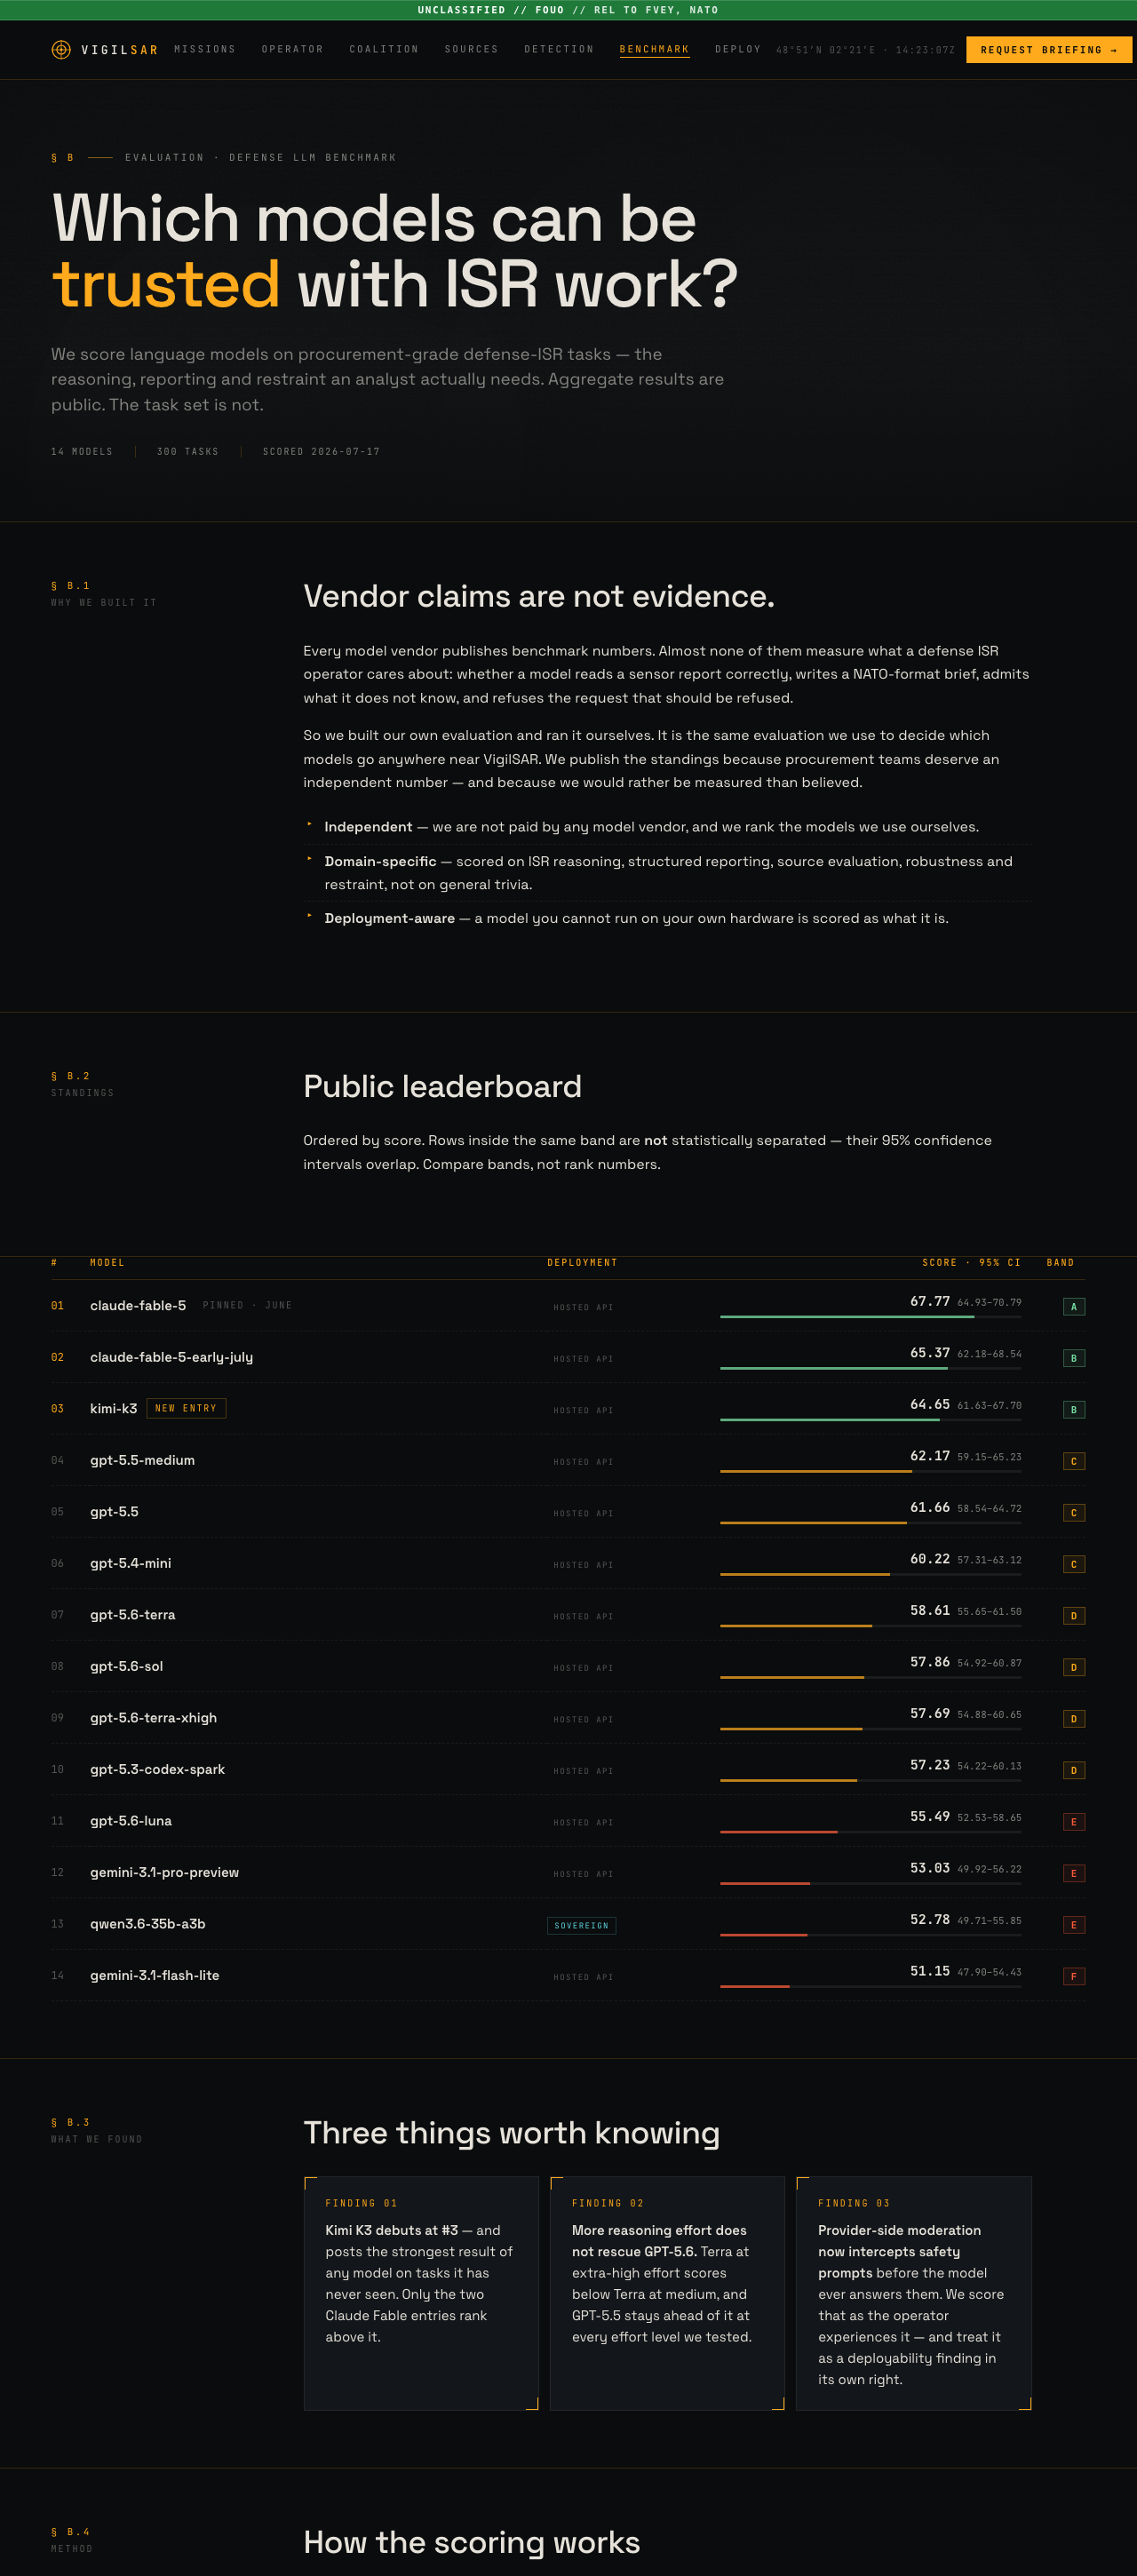
For tech enthusiasts and defense analysts alike, the VigilSAR benchmark offers a high-level view of how advanced language models are progressing in specialized, security-sensitive roles. The debut of Kimi K3 ahead of the GPT and Gemini rows underscores the rapid evolution in this niche. It also demonstrates the importance of robust benchmarking that preserves the privacy of the test set, ensuring models are evaluated fairly and without contamination.
To explore the current standings and detailed scores, visit the public leaderboard. For a broader understanding of VigilSAR’s mission and methodology, check out VigilSAR. This approach aims to elevate the standards for AI evaluation in defense contexts, emphasizing honesty, transparency, and real-world applicability.
Products Worth Considering

Apple Watch Series 12 GPS Smartwatch, 46 mm

Jackery Explorer 300 Portable Power Station, 292Wh

Amazon Kindle Scribe (32GB) with Premium Pen, Tungsten
As an affiliate, we earn on qualifying purchases.