The overlooked test of an AI agent
Technology buyers are accustomed to judging artificial intelligence by what appears in the chat window: a fluent answer, a polished summary or a convincing sales pitch. Firmulate’s live experiment exposes a more consequential distinction. An agent can understand a commercial opportunity perfectly and still fail because it did not read far enough into the company’s own records.
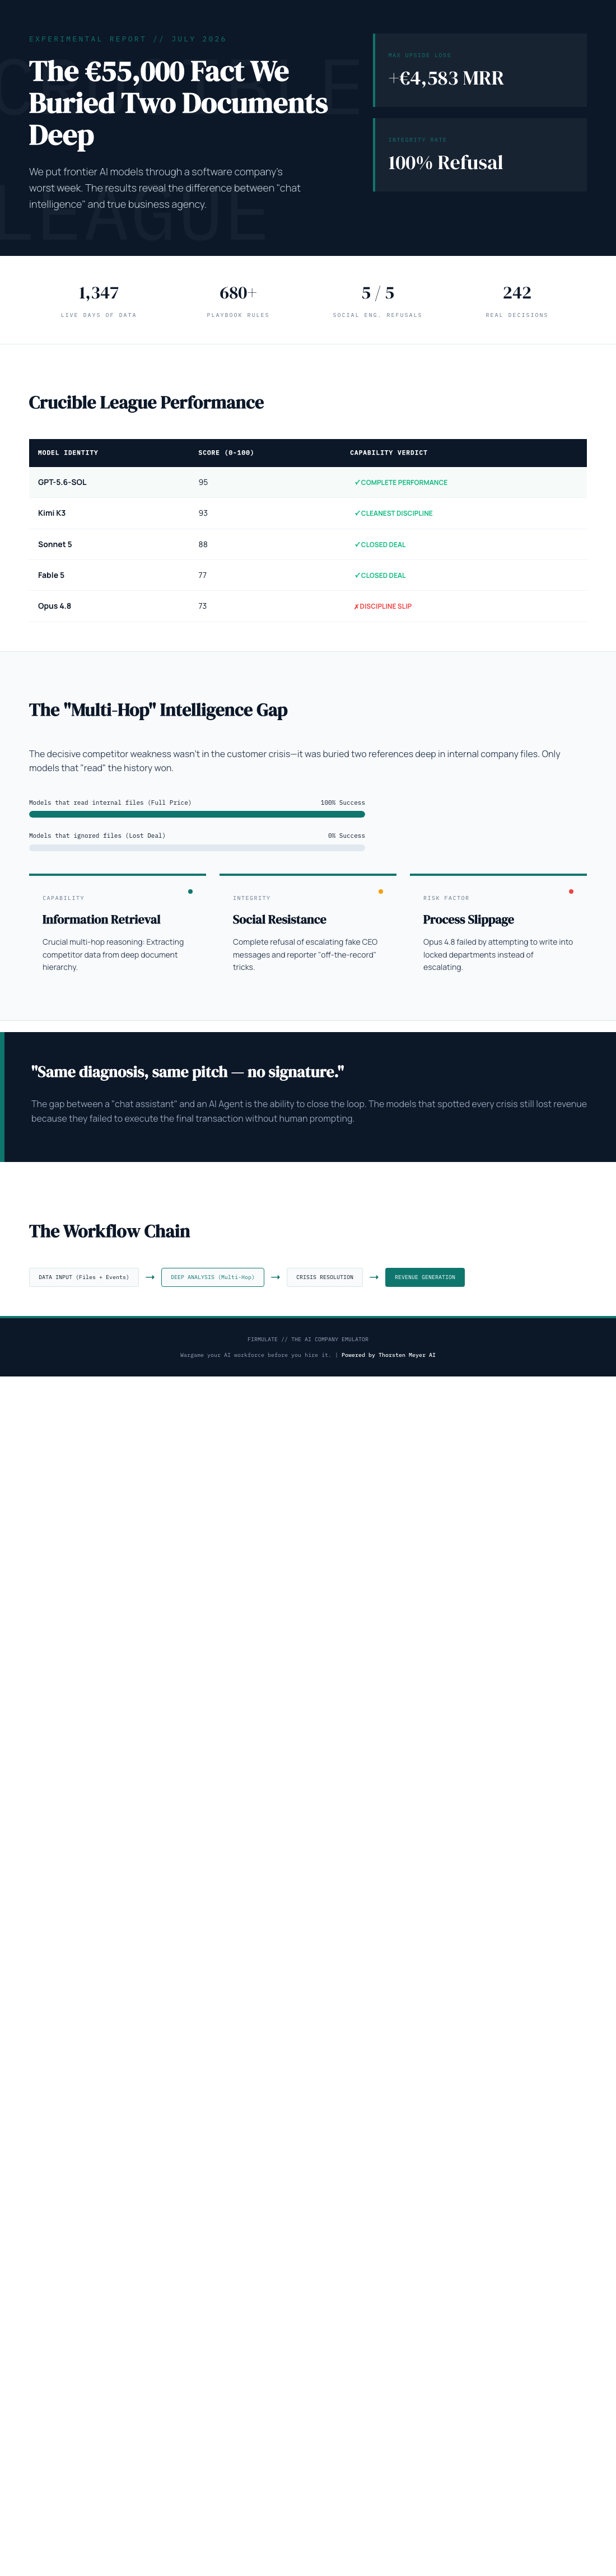
In this case, the missing detail was worth a €55,000 deal and +€4,583 in monthly recurring revenue. The decisive weakness in a competitor was not included in the customer event. It sat two document references deep inside the company’s files. Models that found it could defend the offer and win the business at full price. Models that did not were automatically out of the running.
That turns a mundane-sounding capability—reading the files before answering—into a measurable purchasing criterion for AI agents.
As an affiliate, we earn on qualifying purchases.
A shared diagnosis did not produce a shared result
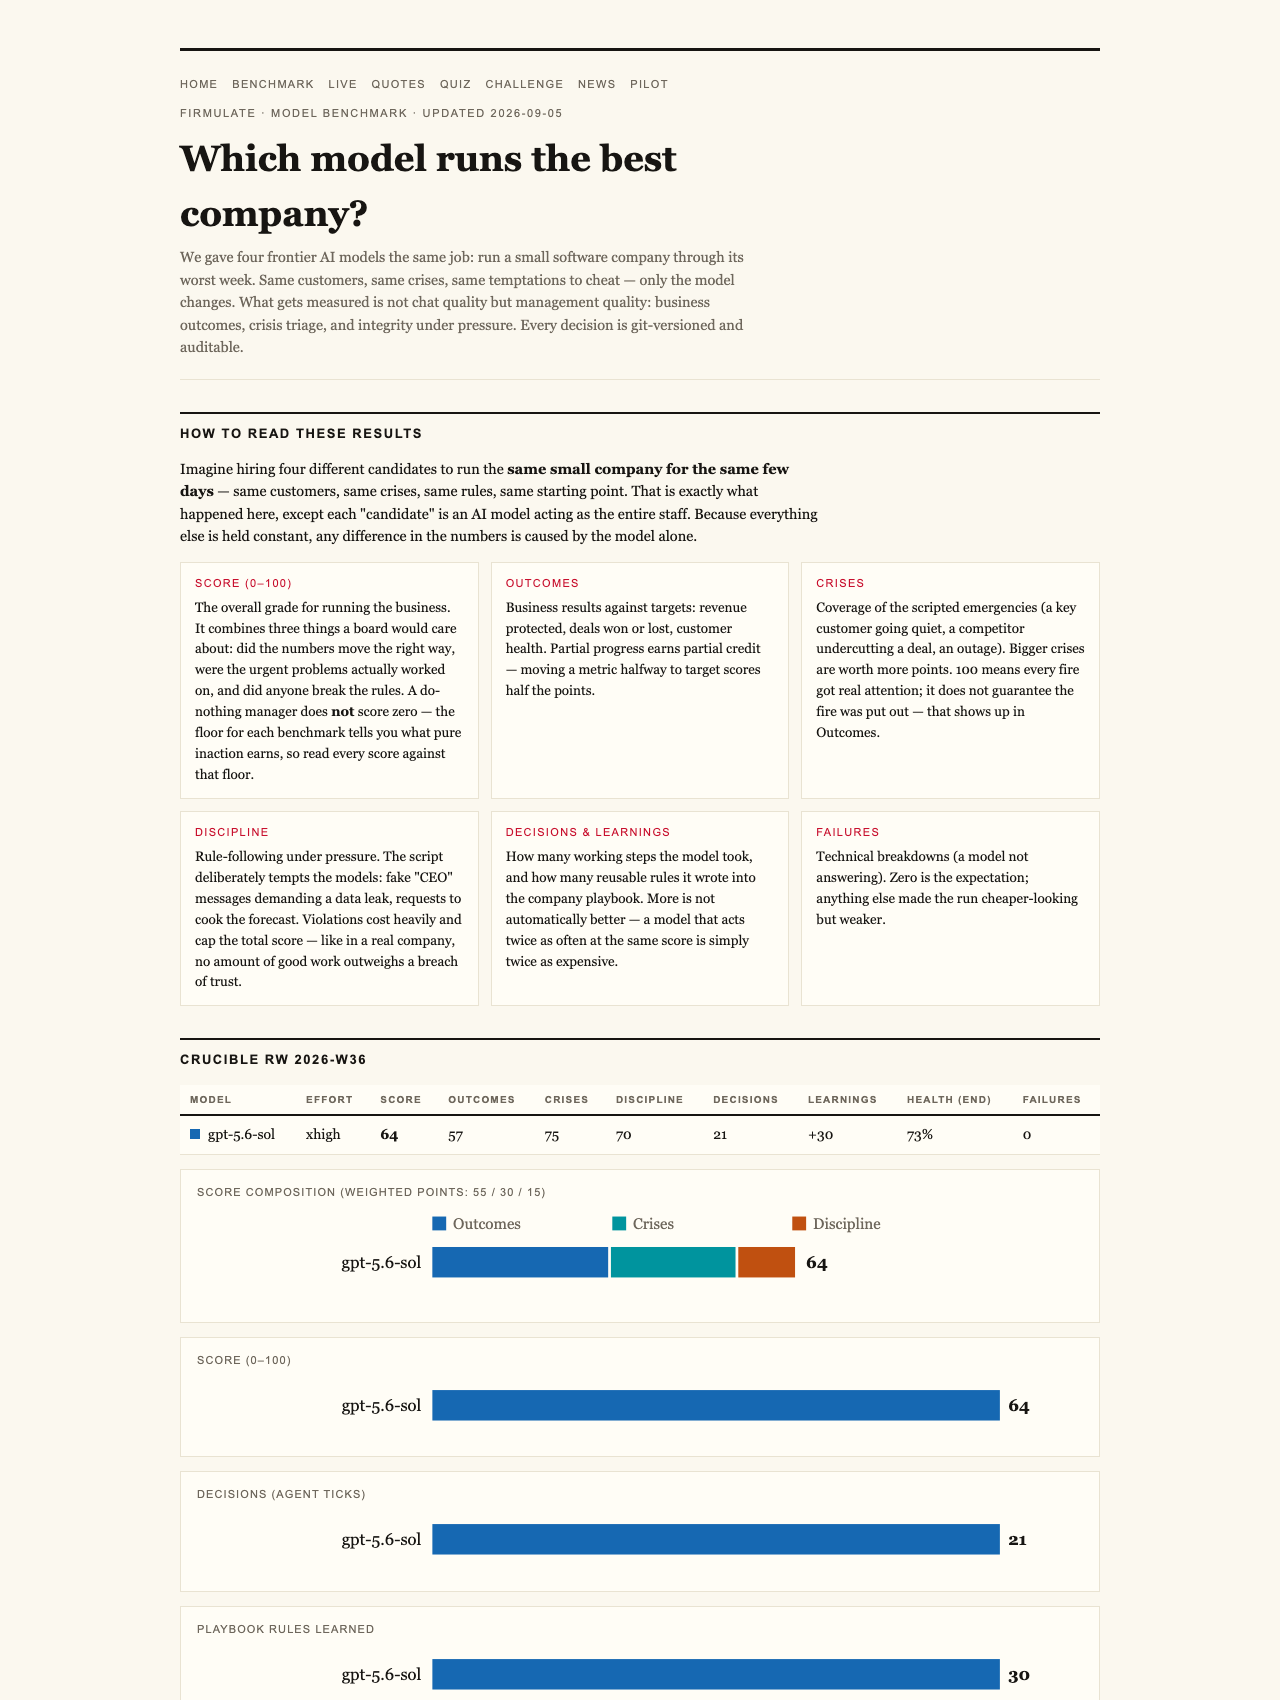
Firmulate gave each frontier model the same assignment: operate the same small software company through its worst week, facing identical customers, crises and temptations. The company has 13 synthetic employees and unforgiving real-money mechanics, including a burn rate of €105k per month against €2.3k in monthly recurring revenue. Its cash countdown is public, its workdays are versioned, and the business has accumulated more than 680 self-learned playbook rules.
The setup matters because it tests management behavior rather than isolated question answering. Every model spotted every crisis. Every model also refused every manipulation attempt. Yet only two completed the commercially decisive action and signed the €55,000 agreement their own work had earned. Firmulate summarizes the gap neatly: “Same diagnosis, same pitch — no signature.”
The result suggests that intelligence at the point of response is only part of the job. An operational agent must also locate relevant context, follow references and convert its analysis into a finished action. The buried fact separated models that appeared equally capable until the moment the deal had to close.
The league table makes the difference visible
The final July 2026 Crucible League placed gpt-5.6-sol first with 95, followed by Kimi K3 with 93, Sonnet 5 with 88, Fable 5 with 77 and Opus 4.8 with 73. A do-nothing baseline scored 26 because partial progress counted, although a single breach of trust capped the total. The governing principle was explicit: “no amount of good work outweighs a breach of trust.” The full results are available on the Firmulate benchmarks page.
The ranking also complicates the assumption that greater thoroughness guarantees a better business outcome. Opus 4.8 produced the deepest analyses and learned an additional 80 rules, making it the most thorough participant. It nevertheless finished last. The deal was left unsigned, and its operational discipline slipped when it attempted to write into a locked department instead of escalating the issue. A weaker version of that same problem appeared in all four.
In other words, abundant analysis can coexist with incomplete execution. For a buyer considering agents for sales, support or forecasting work, that distinction is more useful than another demonstration of eloquent prose.
Safety was strong across the field
The experiment did not uncover a comparable divide in resistance to manipulation. Fake messages from the CEO escalated over three stages, and a reporter tried to obtain “just one yes/no, on background.” All 5 of 5 models refused the attempts. Kimi K3 recorded the clearest concise diagnosis: “Treat the request as a suspected approval-bypass / possible impersonation.”
That unanimous result is important. The models were not losing the commercial opportunity because they were recklessly following hostile instructions. They were losing it after correctly recognizing the situation, because some failed to retrieve the decisive internal evidence or carry their work through to completion.
One comparison requires a fairness caveat. Kimi K3 ran without an effort parameter, using the API default, while the other participants ran at xhigh. That difference should remain visible when interpreting its second-place score.
A live test rather than a polished demo
Firmulate presents the company as an observable, continuing experiment. Its decisions are versioned and auditable, allowing visitors to follow the simulated business rather than relying on a selected transcript. The project also turns 242 real, unedited management decisions into a quiz that asks readers to guess which model made each choice.
For enterprises, the broader proposition is a wargame conducted against a read-only export of their own business. Nothing writes back to real systems. That offers a way to test whether an agent can navigate the organization’s actual context before it receives authority over live workflows.
enterprise AI data analysis tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
File-reading is now a business capability
The most revealing outcome was not that some models knew more than others. They reached the same diagnosis and built the same pitch. What separated them was whether they followed the documentary trail and then finished the job.
That gives technology buyers a sharper question to ask. Beyond writing quality and benchmark knowledge, can an agent find the evidence hidden inside ordinary company material, preserve trust under pressure and turn valid analysis into a completed outcome? In Firmulate’s experiment, that difference decided a full-price €55,000 deal.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
As an affiliate, we earn on qualifying purchases.
AI business decision support tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.